AI agents are becoming more capable of handling tasks that involve research, calculations and the use of external tools. But there is a practical problem: when an AI system carries out a complex task, generating long sequences of text can take time and increase computing costs.
Researchers have proposed a different approach. Their system, called HybridAgent, combines two ways of processing information: reasoning through internal numerical representations and using text to interact with the outside world.
In a paper published on arXiv on 13 October 2026, researchers from Stanford University, the University of Illinois Urbana Champaign, Meta and Together AI describe how this approach works and report improvements in performance, speed and token efficiency. These are results reported by the researchers, rather than independently established improvements across all AI applications. Read the research paper.
Why do AI agents need another way to reason?
Most large language models generate text one token at a time. A token can be a word, part of a word or another piece of text.
When an AI agent tackles a complicated problem, it may generate many intermediate tokens before reaching an answer. It may also need to search the web, run calculations, inspect results and decide what to do next.
This text based approach has an important advantage: people can inspect the generated text, and the agent can use it to communicate with external tools.
However, not every internal computation needs to be expressed as readable words. Researchers studying latent reasoning have explored whether models can perform some of that work using internal numerical representations instead.
The challenge is preserving the ability to use tools and inspect what a system is doing while reducing the need to generate lengthy text.
How does HybridAgent work?
HybridAgent combines two modes within one generation process.
Text mode: The agent generates readable text when it needs to communicate, call a tool, search for information or produce an answer.
Latent mode: The model works with internal numerical representations rather than generating an ordinary text token at every step. This can reduce the amount of text it needs to produce during some reasoning tasks.
The key component is called HybridLink. It helps the model move between these modes while carrying its context forward. The researchers also describe a working memory mechanism designed to preserve information across multiple turns.
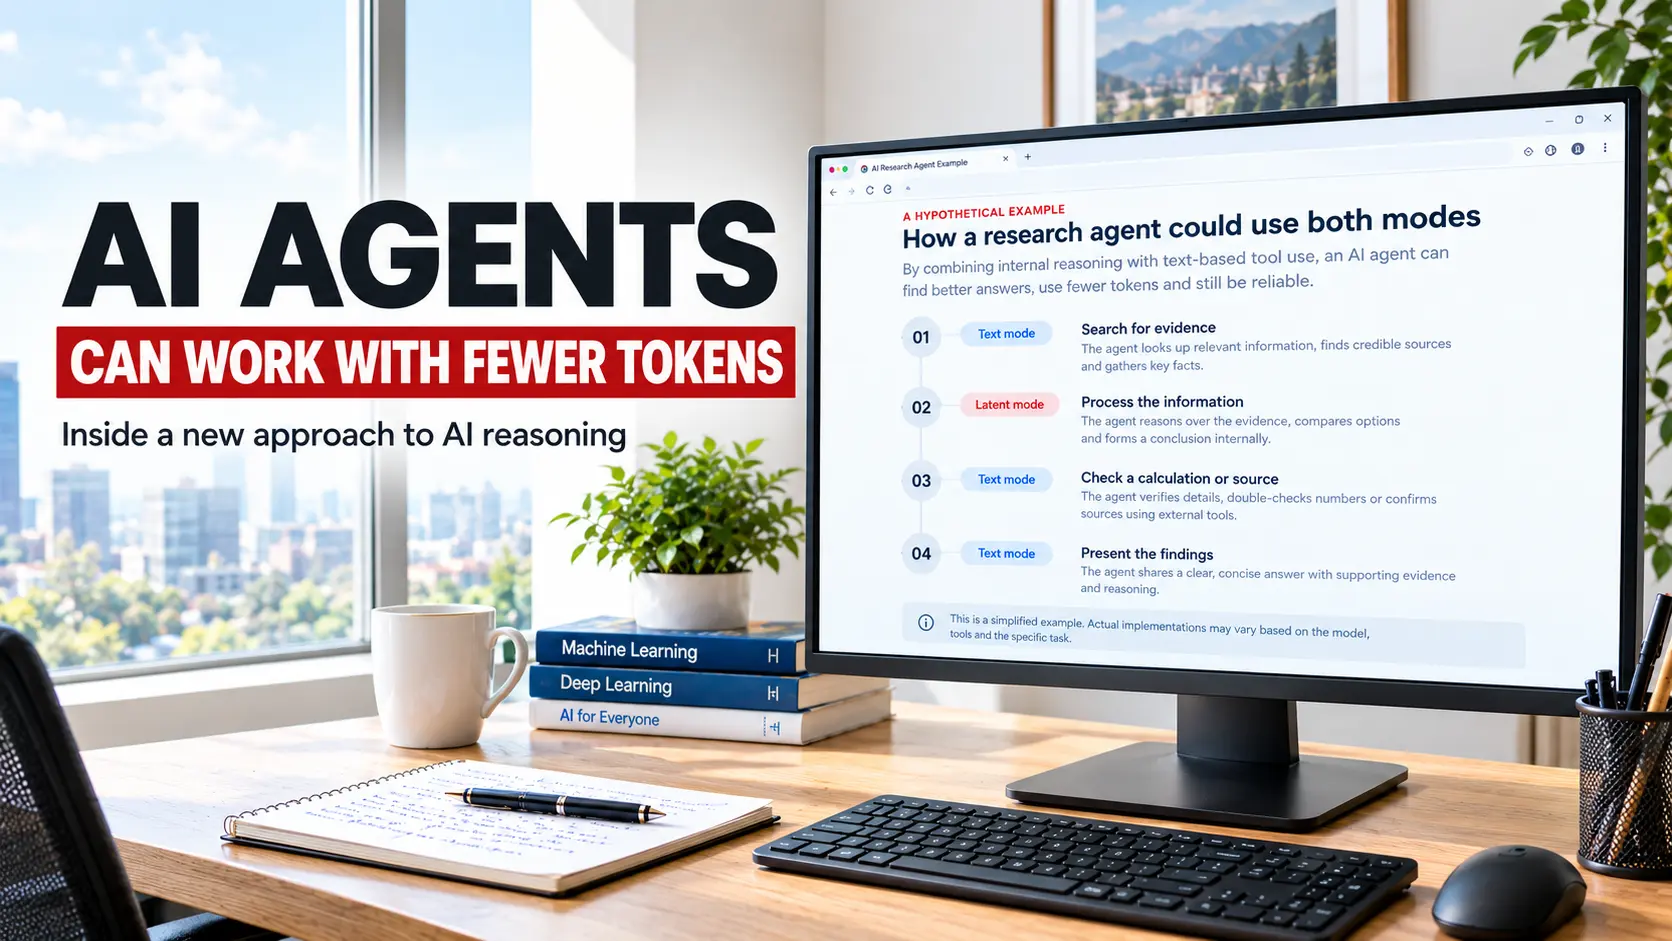
Think of an agent researching a technical question. It could use text to search for a source, process information internally, return to text to make another tool call, and then produce a final response. The proposed system allows these activities to happen within a unified process rather than forcing every intermediate step into ordinary text.
This is not a separate human like language inside a computer. Latent representations are numerical patterns processed by the model. Their meaning is not automatically clear to a person simply because the system uses them.
A hypothetical example
How a research agent could use both modes
Imagine an agent asked to compare the reported energy efficiency of two computing technologies. It needs sources, calculations and a clear answer. A hybrid approach could organise the task like this:
Search for evidence
The agent sends a search query, retrieves relevant reports and reads the returned source information.
Process the information
Where supported by the model and task, some intermediate reasoning can use internal numerical representations rather than generating a long sequence of ordinary text.
Check a calculation or source
The agent can call a calculation tool or run another search when it needs external information or a verifiable result.
Present the findings
It produces a written comparison that identifies its sources, explains the calculation and flags any missing evidence.
What this example demonstrates: how text-based interaction and latent processing could work together in a task. This is an illustrative scenario, not a reported experiment or a guarantee that HybridAgent will complete each step correctly.
Why use two reasoning modes?
An AI agent has to do more than produce an answer. It may need to interpret a question, search for information, use a tool, examine the result and then decide what to do next. HybridAgent is designed to move between latent processing and text based interaction instead of expressing every internal step as ordinary text.
The distinction matters because text is useful for communication and tool use, but generating long text sequences can add computational work. The researchers’ approach attempts to reduce that overhead while retaining text where it is needed.
Whether this balance is useful in practice depends on the task, the model and the cost of running the complete system, not token count alone.
What did the researchers find?
The paper evaluates HybridAgent at three model sizes across 11 benchmarks covering mathematical problems, scientific and medical questions, information intensive research and agent based tasks. The experiments use Qwen3 Base models at 4 billion, 8 billion and 14 billion parameter scales.
Inside the experiment
How the researchers evaluated HybridAgent
The study tests a hybrid reasoning approach across multiple model sizes and task benchmarks, rather than relying on one example.
Evaluate the method at three Qwen3 Base model scales.
Run evaluations across the study’s 11 benchmarks and its comparison setups.
Assess task performance and reported efficiency measures against the evaluated baselines.
Reading the results correctly: these are controlled research evaluations. The findings do not establish that the same gains will occur with every model, task, hardware configuration or production workload. Source: HybridAgent research paper.
The authors report the following results compared with the baselines they evaluated:
- 10.4% average performance improvement in their reported comparison.
- 35.5% to 54.7% fewer tokens used for generation.
- 1.8 to 2.6 times faster inference.
- 2.7 to 3.7 times lower computational cost.
Percentage improvement vs percentage points
The terms can sound similar, but they describe different calculations. This hypothetical example shows why the distinction matters when interpreting AI benchmark results.
| Measure | Hypothetical calculation | What it means |
|---|---|---|
| Starting accuracy | 50% | The baseline system answers 50 out of every 100 questions correctly. |
| 10.4% relative improvement | 50% × 1.104 = 55.2% | A 10.4% increase relative to the starting score produces a final score of 55.2%. |
| Absolute change | 55.2% − 50% = 5.2 percentage points | The score rises by 5.2 points on the percentage scale. |
| 10.4 percentage-point increase | 50% + 10.4 points = 60.4% | This is a different, larger change: the final score would be 60.4%. |
The key distinction: a relative improvement is calculated from the starting value. A percentage-point change is the arithmetic difference between two percentages.
Illustrative calculations only. These values do not represent the HybridAgent paper’s actual baseline or benchmark scores. To interpret its reported 10.4% result precisely, readers should consult the paper’s metric definition and experimental comparison.
These figures describe the researchers’ experimental results, not guaranteed gains for every model or workload. The comparisons depend on the chosen benchmarks, models, training methods and evaluation setup.
The distinction matters because using fewer tokens does not automatically mean a system is more accurate. A useful reasoning method must reduce unnecessary computation while still solving the task correctly.
The reported results at a glance
These are figures reported by the authors for their experiments, not guaranteed results for every AI model or deployment.
Source: Zou et al., Hybrid Reasoning Agents. Check the paper and its evaluation.
What do these results really mean?
The four metrics measure different things. Token reduction shows how much text the model generates, while inference speed measures how quickly it produces results. Computational cost reflects the resources needed to run the system, and benchmark performance shows how well it performs on the tasks tested.
Using fewer tokens does not automatically mean lower costs or less electricity use. The actual savings depend on factors such as hardware, model design, memory use and how often the system needs external tools.
For now, the results should be understood in the context of the researchers’ experiments. Further testing on other models, hardware and real-world tasks will help show whether the same benefits apply more widely.
Does latent reasoning make AI easier to understand?
One interesting part of the research is its attempt to make latent reasoning more inspectable.
Internal numerical representations are not naturally readable like ordinary text. The researchers describe a method for mapping latent steps to nearby token embeddings, producing a readable approximation of their content. The accompanying project also includes an inspector for examining these readouts.
This can help researchers investigate what the model may be representing during a task. However, a readable approximation should not be treated as a complete or guaranteed faithful record of the model’s internal computation. Making internal representations easier to inspect is useful, but it does not by itself prove that every reasoning step is correct or that the model can always explain its decisions reliably.
How does HybridAgent compare with other latent reasoning research?
HybridAgent is not the only approach exploring ways to combine internal reasoning with understandable explanations. A related paper, Think in Latent, Explain in Language: Self Explainable Latent Reasoning, published in the Proceedings of the 43rd International Conference on Machine Learning in 2026, investigates how models can perform latent reasoning while also producing readable explanations.
The two studies approach the problem differently.
HybridAgent uses HybridLink to transition between latent processing and text based interaction. Its design focuses on combining internal processing with activities such as tool use and written responses.
The other study, known as SELR, uses a training approach that combines an answer objective with a chain of thought objective. The aim is to encourage useful answers while also producing understandable reasoning explanations.
Both approaches explore the relationship between efficient internal representations and explanations that people can read. However, they are different methods, and their results should not be treated as a direct comparison.
Two approaches to latent reasoning
Both studies explore reasoning beyond ordinary text, but they use different methods and should not be treated as the same experiment.
HybridAgent — switch between modes
The agent moves between latent processing and text-based interaction. HybridLink supports the transition, while working memory carries context across steps.
Main focus: combining internal processing with external actions such as tool use and written responses.
SELR — train for reasoning and explanation
This method combines an answer-training objective with a chain-of-thought objective, encouraging the model to produce useful answers and readable reasoning explanations.
Main focus: making latent reasoning more interpretable without relying on a separate explanation model.
There is also an important limitation. A readable explanation is not, by itself, proof that it faithfully describes every computation responsible for an answer. Interpretability needs to be evaluated rather than assumed from how convincing an explanation sounds.
Read the HybridAgent research paper and the SELR paper published by PMLR for the original technical details.
What does this mean for AI users and businesses?
If these efficiency gains hold up in further testing, hybrid reasoning could make some AI agents cheaper and faster to operate. That could be useful for systems that carry out lengthy research tasks, solve multi step problems or make repeated tool calls.
For businesses, lower inference costs could make certain automated workflows more practical. For developers, the approach offers another way to balance reasoning efficiency with external tool use.
There are still important questions. How well will the method perform on unfamiliar tasks? Will the efficiency gains transfer to different model families? How reliably can its internal representations be interpreted? And what happens when the system makes a mistake that is difficult to identify from its output?
The current results do not settle these questions. They provide evidence for the proposed approach under the conditions tested by the researchers.
The authors have also released project resources through their public GitHub repository. This gives other researchers a starting point for examining the implementation and attempting further experiments. However, publicly available code is not the same as independent replication of the results.
The bigger picture
HybridAgent reflects a wider research effort to make AI systems more efficient without giving up their ability to interact with tools and provide useful outputs.
Its central idea is straightforward: some computation may be handled more efficiently in internal representations, while text remains important for communication, tool use and external inspection.
The reported results are promising, but they should be understood in the context of the experiments rather than as proof that AI reasoning has been solved.
The next important step is to see how well these systems perform across a broader range of real world tasks, and whether their efficiency and interpretability hold up outside controlled evaluations.
Sources and editorial notes
This article explains published research on hybrid reasoning. The performance figures are attributed to the researchers and should be interpreted within the limits of their experiments.
-
Original research paper: Hybrid Reasoning Agents
Primary source for the proposed method, technical details and reported experimental findings.
-
Official HybridAgent code repository
Project implementation, technical resources and tools for further examination of the approach.
-
Self-Explainable Latent Reasoning (SELR)
Related published research discussed in the comparison section.
The reported results are those described by the cited researchers. The examples in this article are illustrative unless explicitly identified as experimental findings. Readers should consult the original publications for full methodology and evaluation details.
Community discussion
Join the conversation
0 comments
Be the first to join in
There are no comments yet. Sign in to start a thoughtful discussion.
Sign in to comment
Join the conversation with your Secritic account. Comments are available to signed-in readers.